
We see Datalab as the bridge that helps us transform those old formats into something modern and easy to work with.
High-precision document intelligence.
We are a research lab that trains document intelligence models, trusted by frontier AI labs, museums, and enterprises where accuracy is non-negotiable.
TRUSTED BY


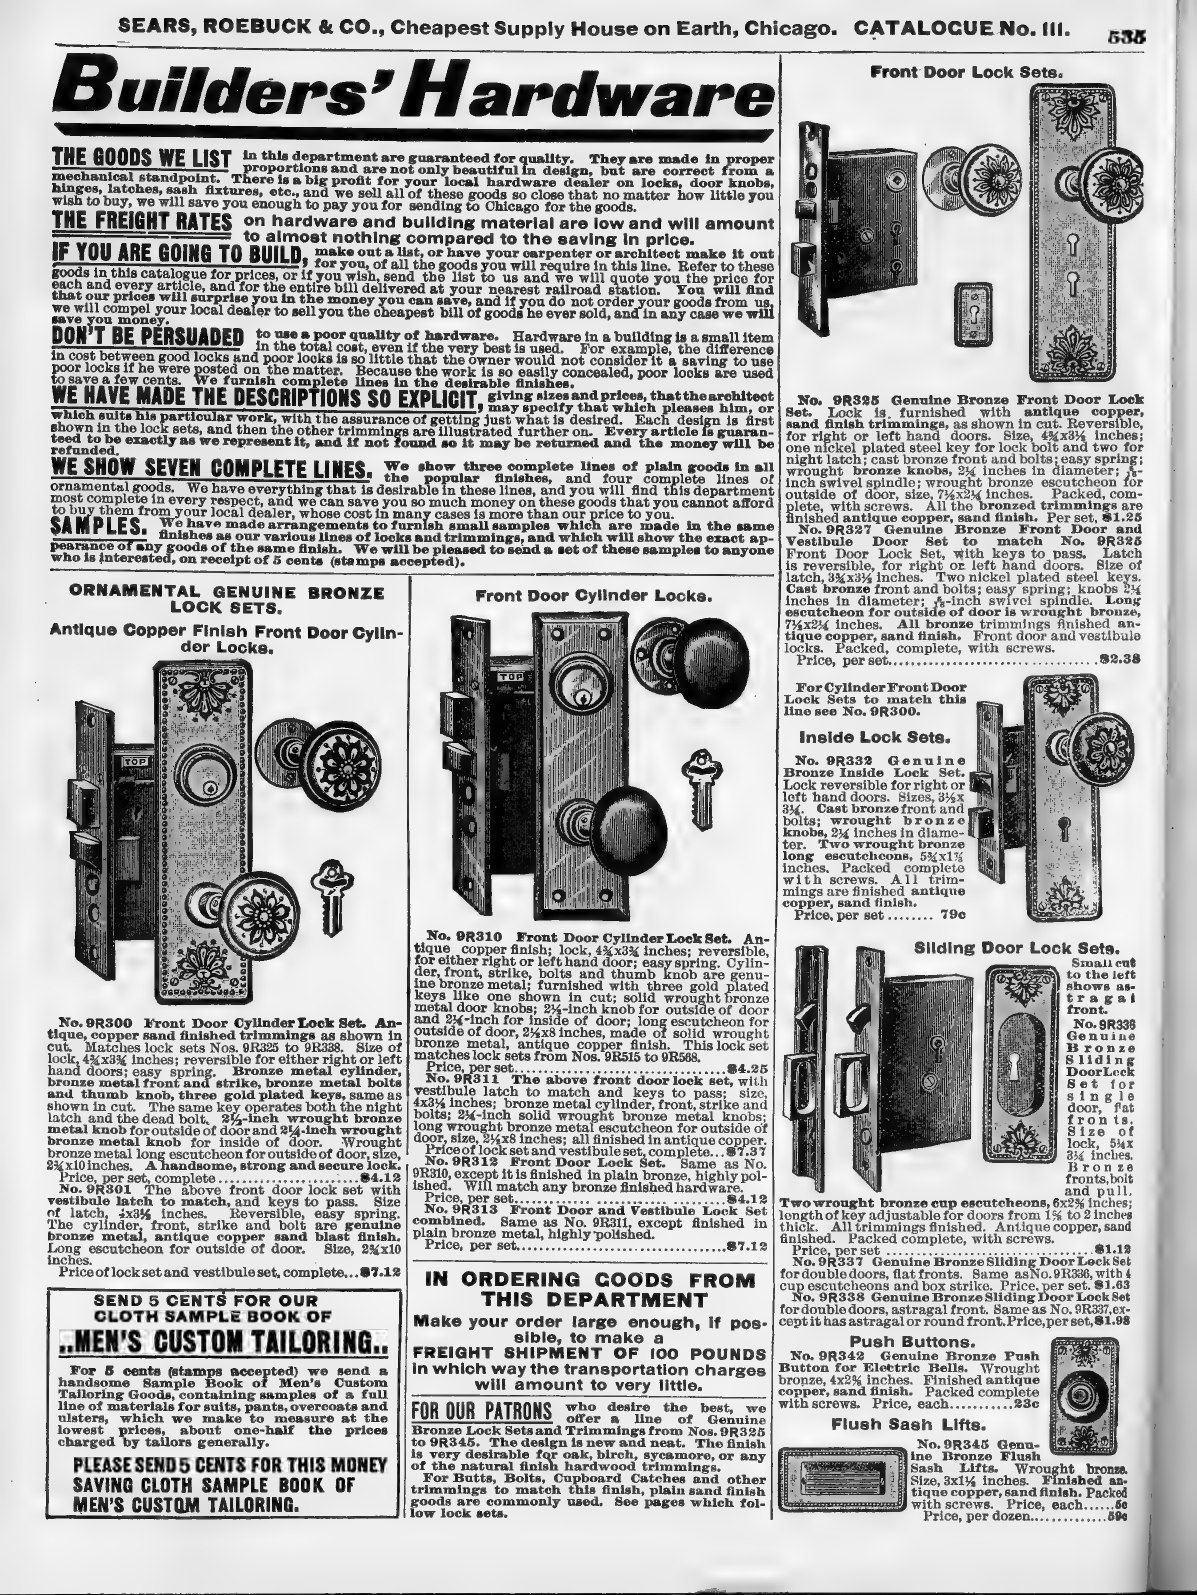 1 HDR2 H13 H14 TEXT5 H16 TEXT7 TEXT8 H19 TEXT10 TEXT11 H112 TEXT13 TEXT14 H115 H116 IMG17 TEXT18 TEXT19 H120 IMG21 TEXT22 TEXT23 TEXT24 TEXT25 H126 TEXT27 H128 TEXT29 TEXT30 H131 IMG32 TEXT33 TEXT34 TEXT35 TEXT36 H137 TEXT38 IMG39 IMG40 H141 TEXT42 TEXT43 TEXT44 TEXT45 H146 TEXT47 H148 TEXT49 H150 H151 TEXT52 TEXT
CONFIDENCE 96.9%
- 1 Page Header Page Header 0.977
- 2 Section Header Builders' Hardware 0.959
- 3 Section Header THE GOODS WE LIST 0.984
- 4 Text In this department are guaranteed for quality. They are made in proper proportions and are not only beautiful… 0.965
- 5 Section Header THE FREIGHT RATES 0.980
- 47 more regions detected
Models deployed for any workflow
Each processor is rigorously benchmarked and designed for easy composition in your workflows.
P · 01 Convert
Use Chandra 2.5 to convert PDFs, spreadsheets, slides and more to markdown, HTML, and JSON, in fast, balanced, or accurate mode. Add word-level bounding boxes, chart data, and structured figure descriptions.
P · 02 ExtractPull the fields you define into JSON, with citations and a confidence score on every field. Four modes, from turbo to accurate.
P · 03 SegmentIdentify natural boundaries between documents that were originally combined into one file.
P · 04 EvalEvaluate the quality of output, using our criteria or your own rubrics for quality.
Measured in the open.
OmniParseBench is our open benchmark: 16,288 pass/fail tests, every parser we could run, and every verdict public. Datalab accurate scores 93.5, ahead of Reducto, LlamaParse, Mistral OCR, Extend, and Azure.
Compose. Deploy. Monitor.
One pipeline runtime — from a single API call to 1B+ pages in a day.
Wire processors into a pipeline.
Pick the processors you need. Compose them in the playground. Promote a versioned pipeline to production.
Run our models anywhere.
Managed cloud, in your VPC, or fully air-gapped. We own the models — so you choose the network.
Monitor improvements and flag regressions.
Continuous evals against rubrics and a reference corpus — quality improves as we ship model updates, and any regression gets flagged.
Trusted in countless mission-critical workflows.
Same engine — different documents. From training corpora to clinical trials to claims forms, every vertical gets the same bbox-precise parsing.
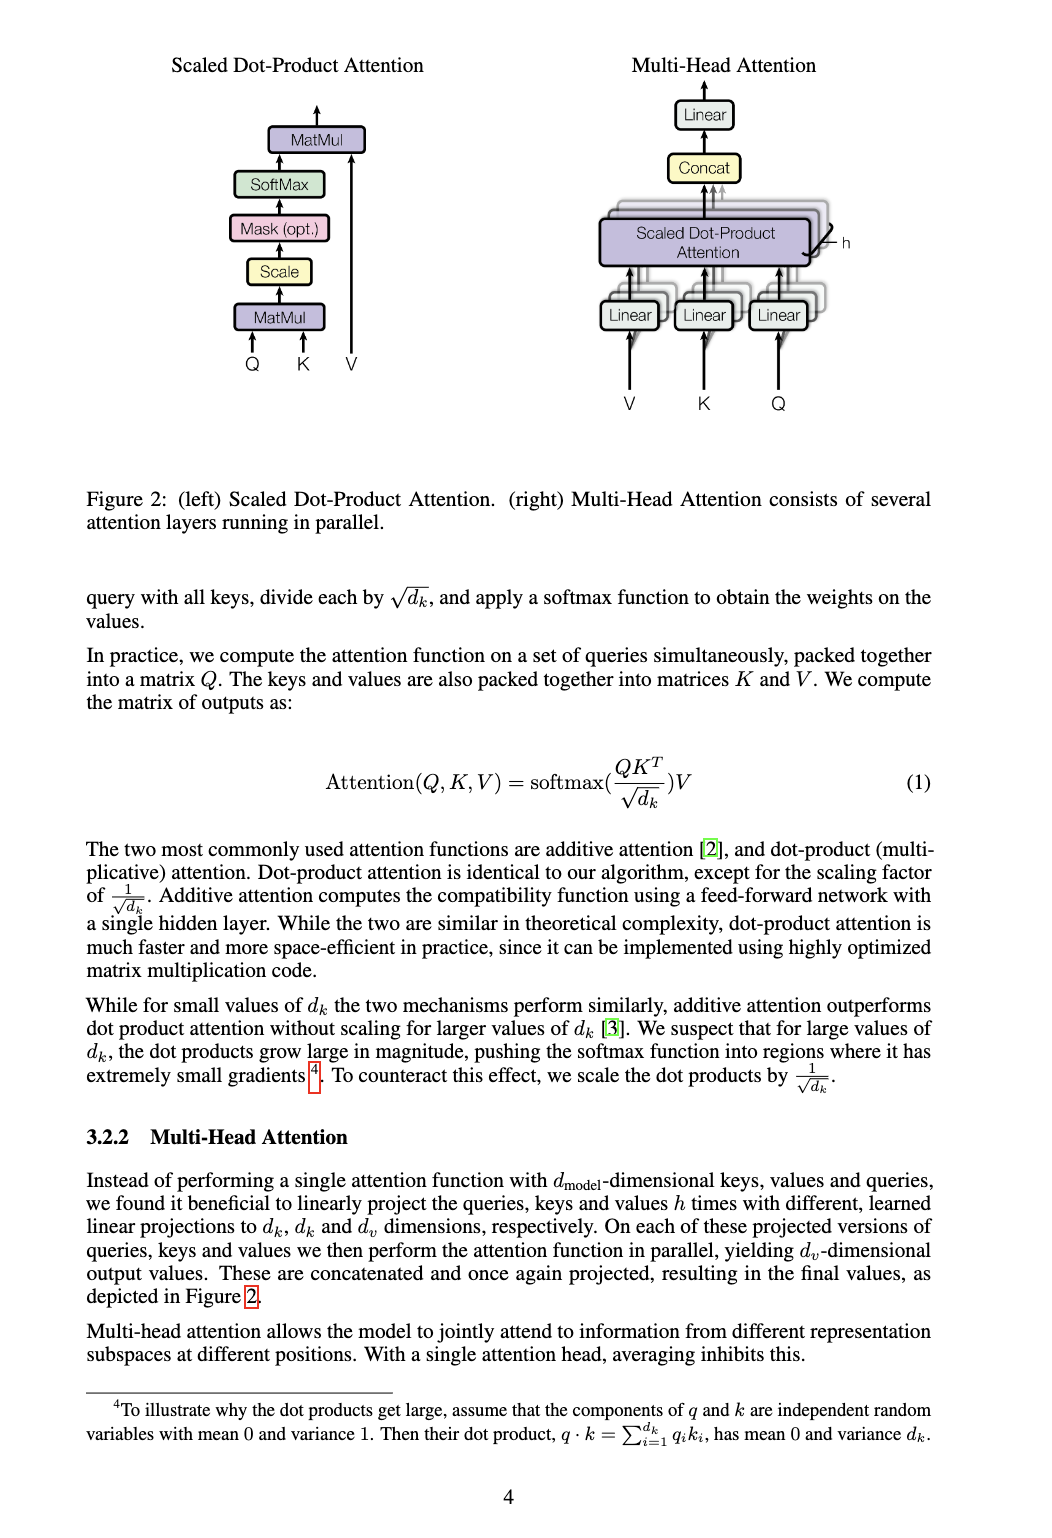 1 CAP2 FIG3 CAP4 FIG5 CAP6 TEXT7 TEXT8 EQN9 TEXT10 TEXT11 H112 TEXT13 TEXT14 FN15 FTR
15 blocks 96.9%
Training-grade corpora.
Parse web crawls, scientific papers, multilingual sources, and 1000+ page books into clean, citation-ready training data.
- Multilingual web corpora
- Scientific papers (PDF + LaTeX)
- Long-document books (1000+ pp)
- Math, charts, diagrams
"Working with Datalab has helped us move faster and solve complex edge cases with our documents. We need highly accurate document processing, and Datalab has been a key part of our data infrastructure. We're excited to continue to partner with Datalab."
— S., Member of Technical Staff, Frontier Lab
1B+ pages in a day. Zero infrastructure.
Burst at scale on our GPUs. We allocate the workers, you pay per page processed. In production at the largest AI labs and Fortune 500 enterprises.
Open Source first.
Marker, Surya, Chandra, and Indra are our open source models — used by thousands of teams, 75k+ stars combined. Our managed platform handles scaling infrastructure, includes better proprietary models, and has enterprise-grade reliability.
Marker + Surya
High-throughput OCR engine for resource-constrained environments. Covers 90+ languages.
62k ★
Chandra Our flagship open OCR model. Works on the messiest docs and the hardest edge cases.
12.5k ★
Indra A 1M-parameter OCR model that reads handwriting, 80+ languages and pages at any angle, fast on a plain CPU.
Run it on our infrastructure. Or yours.
Because we own the models, you can run them anywhere — including networks that don't touch the internet.
Managed Cloud
Sign up, get an API key, ship in minutes. Free tier available.
- Auto-scaling
- SOC 2 Type II
- 99.99% uptime
- Pay-as-you-go
VPC Deployment
Datalab runs inside your private cloud. Compliance, residency, control.
- AWS / GCP / Azure
- Custom BAA / DPA
- Sub-processor transparency
- Dedicated support
On-prem · Air-gapped
For research labs and regulated environments where data cannot leave the network.
- No internet required
- Full model weights
- Custom hardware support
- White-glove deployment
What we shipped lately.
Model releases, benchmarks, and research notes from the team.
Word boxes that hold up on handwriting
Tighter word boxes on handwritten and scanned pages, and confidence scores that stop flagging words that are fine.
Find the fillable fields on any form
Form field detection finds 87% of form fields in our tests, at a median 1.1 s per page, with each field's type, box, and label.
Indra OCR 1.1: handwriting, 80+ languages and pages at any angle
Indra OCR 1.1 reads handwriting, OCRs 80+ languages on scans, and straightens pages at any angle. OmniParseBench headline 71.4 with --math, still on CPU.
Start parsing.
Free tier available. No credit card required.